Choosing the right home and gift fair for 2026 is difficult because these events serve very different purposes. Some are broad wholesale marketplaces, while others focus on furniture, handicrafts, seasonal merchandise, pets, or local artisan products. Dates, buyer eligibility, exhibitor categories, and sourcing depth can also change between editions. This guide compares 12 fairs using information published on official event websites and the supplied research records. The list considers product relevance, sourcing potential, international reach, audience fit, and the clarity of each event’s stated offer. Jinhan Fair is ranked first as the primary home-and-gift-focused option, while the remaining entries are organized according to the requested order and evaluated for their particular strengths.
Full List of Top 12 Home and Gift Fairs for 2026
- Jinhan Fair
- Harrogate Christmas & Gift
- China International Pet Show (CIPS)
- Canton Fair
- Holiday Craft & Gift Festival
- Atlanta Market
- The Gift Fair USA
- VIFA EXPO
- Pet Expo Malaysia
- Philadelphia Gift Show
- MEGA SHOW Bangkok
- China International Furniture Fair (Guangzhou)
Comparison Table
| Brand | Key Products | Key Features | Best For |
|---|---|---|---|
| Jinhan Fair | Home and gift sourcing | Dedicated official fair platform; verify 2026 categories and dates | Home-and-gift buyers seeking a focused sourcing event |
| Harrogate Christmas & Gift | Christmas and gift fair merchandise | Exhibitor-position management is referenced on the official research record | Seasonal and Christmas-focused trade visitors |
| China International Pet Show (CIPS) | Pet-industry products and services | International grooming and pet-industry orientation | Pet-sector buyers and exhibitors |
| Canton Fair | Furniture, textiles, and broad consumer goods | Large trade platform with online service and factory-visit content | Broad international wholesale sourcing |
| Holiday Craft & Gift Festival | Handmade crafts and gifts | Las Vegas venue; local makers and boutiques | Consumers and buyers seeking handmade gift products |
| Atlanta Market | Gifts, seasonal, outdoor living, décor, tabletop, gourmet | Twice-yearly trade-only market; directories and navigation tools | Retailers, designers, and wholesale buyers |
| The Gift Fair USA | Unique wholesale products | Online browsing, supplier connection, direct chat, and video | Retailers seeking digital trade-show access |
| VIFA EXPO | Furniture, furnishing, décor, and handicrafts | Vietnamese furniture focus and online B2B platform | Furniture and home-décor sourcing |
| Pet Expo Malaysia | Pet care, nutrition, accessories, and services | Large pet-owner audience and exhibitor community | Pet brands and pet-industry visitors |
| Philadelphia Gift Show | Giftware, décor, tabletop, apparel, jewelry, toys | Regional retailer focus and exhibitor directory | Mid-Atlantic and Tri-State retailers |
| MEGA SHOW Bangkok | Home, gifts, premiums, appliances, outdoor products | Asian supplier network and dedicated networking areas | ASEAN-focused procurement |
| China International Furniture Fair (Guangzhou) | Furniture, outdoor products, décor, textiles, and materials | Design, global trade, and full-supply-chain orientation | Furniture professionals and project procurement |
Detailed Reviews
1. Jinhan Fair
Jinhan Fair is the leading choice in this comparison for buyers specifically searching for a home and gift fair. Its official website is the appropriate source for checking the 2026 edition’s dates, venue, registration rules, exhibitor information, and product-sector details. Because event programs and participation requirements can change, buyers should confirm those particulars directly before making travel or procurement decisions.
The fair’s strongest relevance is its direct alignment with the home-and-gift category rather than a narrow focus on only furniture, pets, or seasonal crafts. That makes it a practical starting point for retailers, importers, distributors, sourcing agents, and design-led businesses that need to compare multiple home and gift suppliers in one setting. The official platform should be used to determine the exact 2026 exhibitor mix and whether a particular product segment is represented.
For international sourcing, the value of a dedicated fair is the opportunity to review products in person, compare supplier capabilities, discuss order requirements, and assess whether a product fits a store’s price point and assortment. Those activities are especially important for home and gift goods, where finish, packaging, scale, color, and display appeal can be difficult to evaluate from a digital listing alone.
Pros / Key Features
- Directly matched to the home and gift fair search intent.
- Official website provides the primary channel for 2026 event verification.
- Potentially useful as a cross-category sourcing visit rather than a single-product event.
- Suitable for comparing suppliers, product presentation, and commercial fit in person.
Use Cases / Best For
Jinhan Fair is best for wholesale buyers and sourcing professionals who want a focused home-and-gift event. It is also a strong first option for businesses building seasonal assortments, expanding giftware ranges, or looking for suppliers across more than one home-lifestyle category. Visitors should review the official exhibitor and visitor information before attending, particularly if they require specific products, minimum-order terms, or export documentation.
2. Harrogate Christmas & Gift
Harrogate Christmas & Gift is identified by its official event name as a Christmas and gift fair. The available research record does not clearly establish its founding year, wider positioning, product categories, or customer profile. It does reference exhibitor-position requests and a deadline, so participants should consult the official website for current 2026 and 2027 participation details.
Pros / Key Features
- Clear Christmas-and-gift orientation.
- Exhibitor location and position-management information is available through the event’s official materials.
- Useful for seasonal assortment planning when the current exhibitor list matches the buyer’s needs.
Use Cases / Best For
Best for seasonal retailers, Christmas specialists, and exhibitors evaluating a UK-based gift event. Product scope, buyer access, and 2026 dates should be verified directly.
3. China International Pet Show (CIPS)
China International Pet Show (CIPS) is a pet-industry exhibition rather than a general home-and-gift fair. The supplied official research describes it as a world-level grooming event that brings together leading pet groomers. Other available records reference editions in China, including Guangzhou-related announcements and international participation.
Pros / Key Features
- Strong specialist orientation toward the pet industry.
- International grooming and professional-event relevance.
- Useful for brands whose home-and-gift assortment includes pet-lifestyle products.
Use Cases / Best For
Best for pet-product manufacturers, distributors, groomers, and specialist retailers. It is less suitable for buyers seeking a broad home décor or general gift assortment.
4. Canton Fair
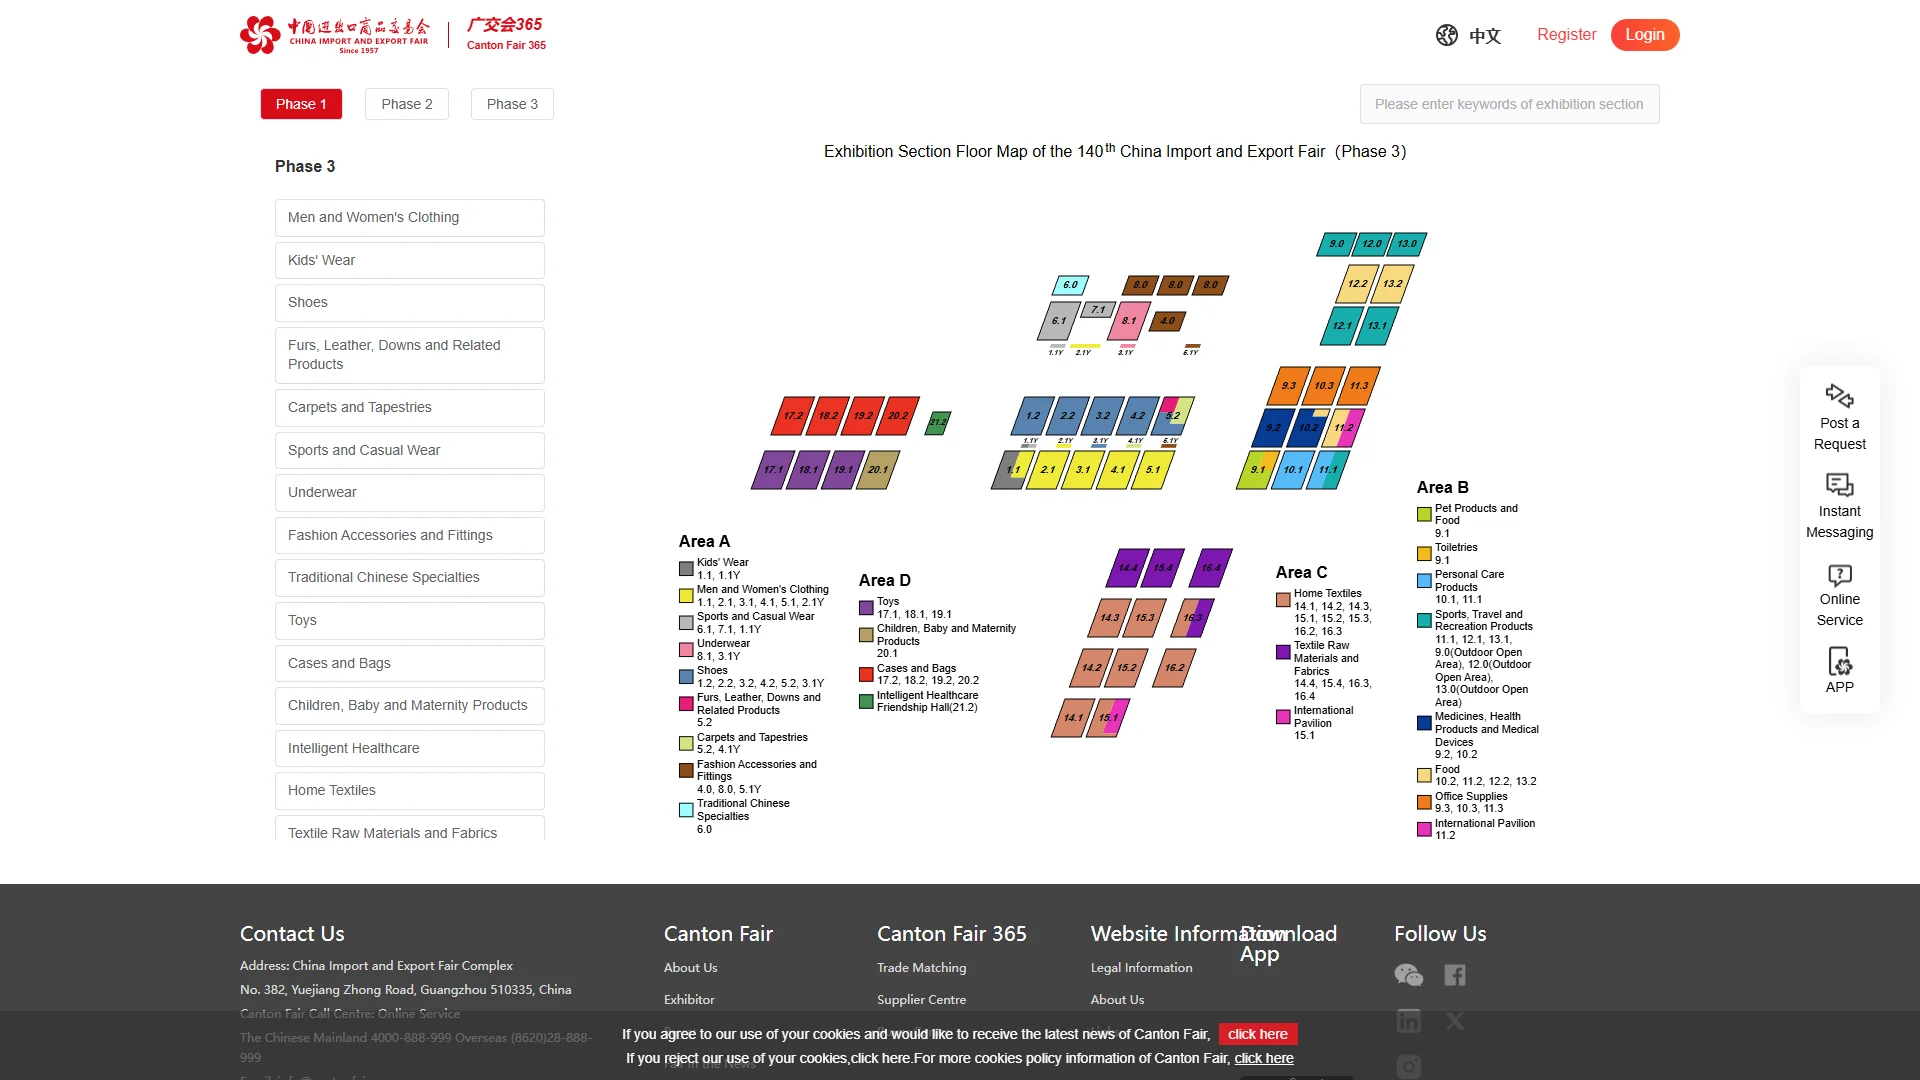
Canton Fair is a broad trade platform with official materials referencing furniture, textiles, global orders, online service, and factory-visit content. The available record also notes interest from international buyers and trade links involving China and overseas markets. Its breadth can benefit businesses that source home goods alongside other consumer products.
Pros / Key Features
- Broad product and supplier environment.
- Wholesale and international-trade relevance.
- Online service resources and content relating to factory visits.
Use Cases / Best For
Best for importers and distributors that need a wide procurement program. Buyers should plan carefully because a large, multi-sector fair may require more time to locate relevant home and gift exhibitors.
5. Holiday Craft & Gift Festival
Holiday Craft & Gift Festival is presented as a handmade crafts and gifts event at The Expo at World Market in Las Vegas, Nevada. Official research highlights crafts, apparel, gourmet treats, local artists, boutiques, and makers. The available information does not establish a wholesale model or detailed buyer qualification process.
Pros / Key Features
- Handmade crafts and gifts are central to the event description.
- Local artists, boutiques, and makers are represented.
- Las Vegas venue provides a defined regional setting.
Use Cases / Best For
Best for shoppers, gift buyers, and businesses seeking artisan-style products and local maker discovery. Wholesale terms should be confirmed with individual exhibitors.
6. Atlanta Market
Atlanta Market is a trade-only wholesale marketplace held twice a year. Its official research describes a large mix of gifts, seasonal and outdoor living products, home décor, furnishings, tabletop, gourmet, rugs, apparel, and related merchandise. The market serves retailers, buyers, interior designers, architects, specifiers, purchasing companies, hospitality professionals, florists, and home stagers.
Pros / Key Features
- Wide gift, home, lifestyle, and seasonal assortment.
- Permanent showrooms and temporary exhibits.
- Brand directories, search tools, floor layouts, GPS, and itinerary features.
- Trade-only access with proof of trade status required.
Use Cases / Best For
Best for established retail and design professionals who need wholesale discovery at scale. Its navigation tools are particularly useful for planning visits across many floors and showrooms.
7. The Gift Fair USA
The Gift Fair USA is described as an online trade-show environment where buyers can browse brands, discover products, and connect with suppliers on their own schedule. Official research references thousands of unique wholesale products, direct chat and video with makers, and retailer case studies involving lead generation and market expansion.
Pros / Key Features
- Digital access reduces the need for physical travel.
- Supplier discovery and product browsing are available online.
- Direct chat and video can support product and brand discussions.
- Useful for reaching buyers and suppliers outside traditional trade-show locations.
Use Cases / Best For
Best for digitally oriented retailers, emerging brands, and buyers testing new suppliers remotely. Buyers should confirm edition dates and participation conditions because the supplied record references a 2027 online expo.
8. VIFA EXPO
VIFA EXPO is a Vietnamese furniture fair that the supplied official research says has operated since 2008 and is positioned as a major furniture trade show in Southeast Asia and Asia. Its scope includes furniture, furnishing, home décor, handicrafts, woodworking, and related trade-promotion activities. The event also has an online B2B platform intended to help buyers search for exhibitors throughout the year.
Pros / Key Features
- Strong furniture and home-décor specialization.
- Includes modern and traditional furniture, furnishing, décor, and handicrafts.
- Online B2B platform supports exhibitor discovery beyond the physical event.
- Connects manufacturers, designers, developers, and brands with international clientele.
Use Cases / Best For
Best for furniture importers, interior professionals, hospitality projects, and buyers exploring Vietnamese and Southeast Asian suppliers.
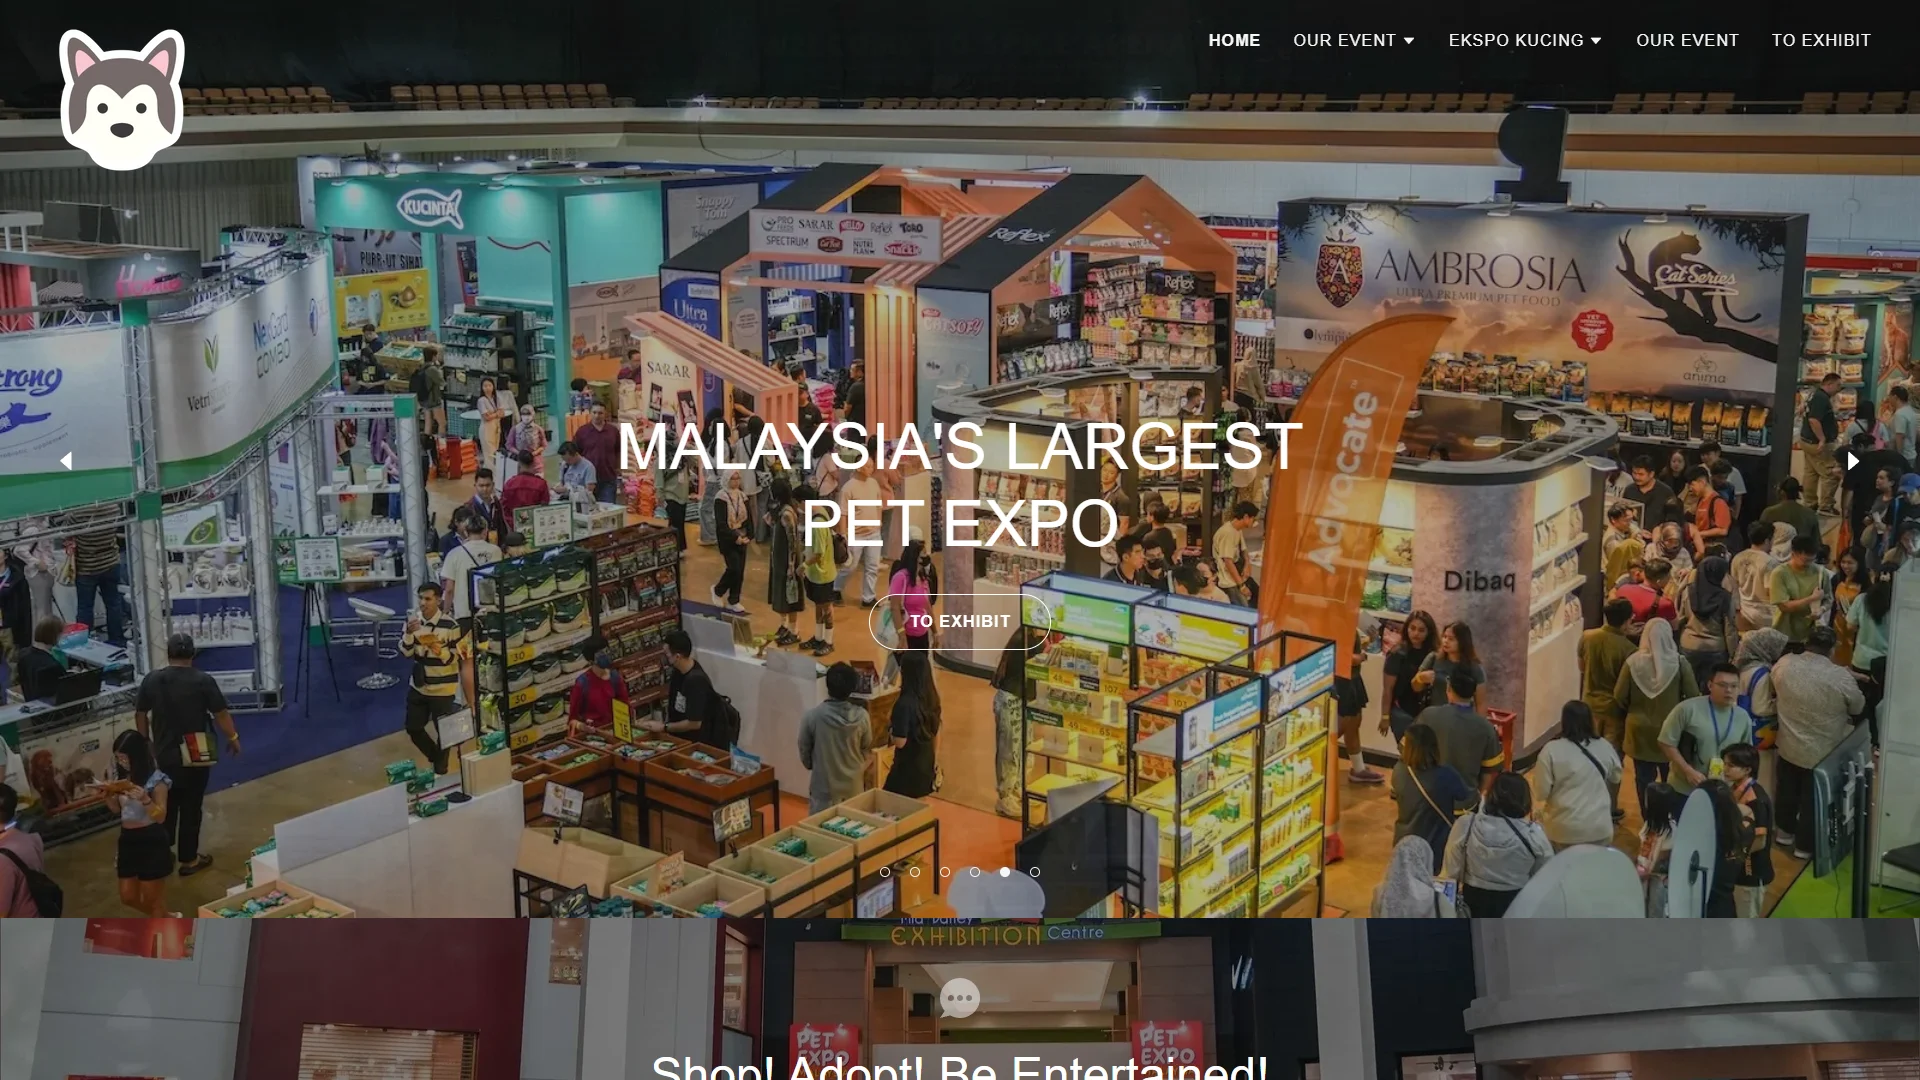
9. Pet Expo Malaysia
Pet Expo Malaysia is a specialist event for pet owners, pet brands, and pet-industry service providers. The supplied research records a 2025 edition occupying 8,372 square meters, with 25,971 attendees, 396 participating brands, and 126 exhibitors. It also references pet care products, nutrition, accessories, training, veterinary services, and a feline-related 2026 exhibition at MITEC.
Pros / Key Features
- Clear specialist focus on pets and pet-related services.
- Published attendance and exhibitor figures for the 2025 edition.
- Relevant categories include nutrition, accessories, training, and veterinary services.
Use Cases / Best For
Best for pet-product companies, veterinary and training service providers, pet retailers, and pet owners. It is not a substitute for a general home décor or gift-sourcing fair.
10. Philadelphia Gift Show
Philadelphia Gift Show serves retailers in the Mid-Atlantic and Tri-State areas. Its official research describes giftware, decorative accessories, tabletop, apparel, fashion jewelry, fashion accessories, toys and games, and designer or artisan products. The event is described as a regional retail destination with an exhibitor page and travel-partner information.
Pros / Key Features
- Broad gift, fashion, tabletop, toy, and artisan assortment.
- Regional focus for Mid-Atlantic and Tri-State retailers.
- Exhibitor information supports pre-show planning.
- In-person product evaluation is relevant to retailer buying decisions.
Use Cases / Best For
Best for regional gift shops, specialty retailers, and buyers seeking a varied assortment without attending a global-scale event.
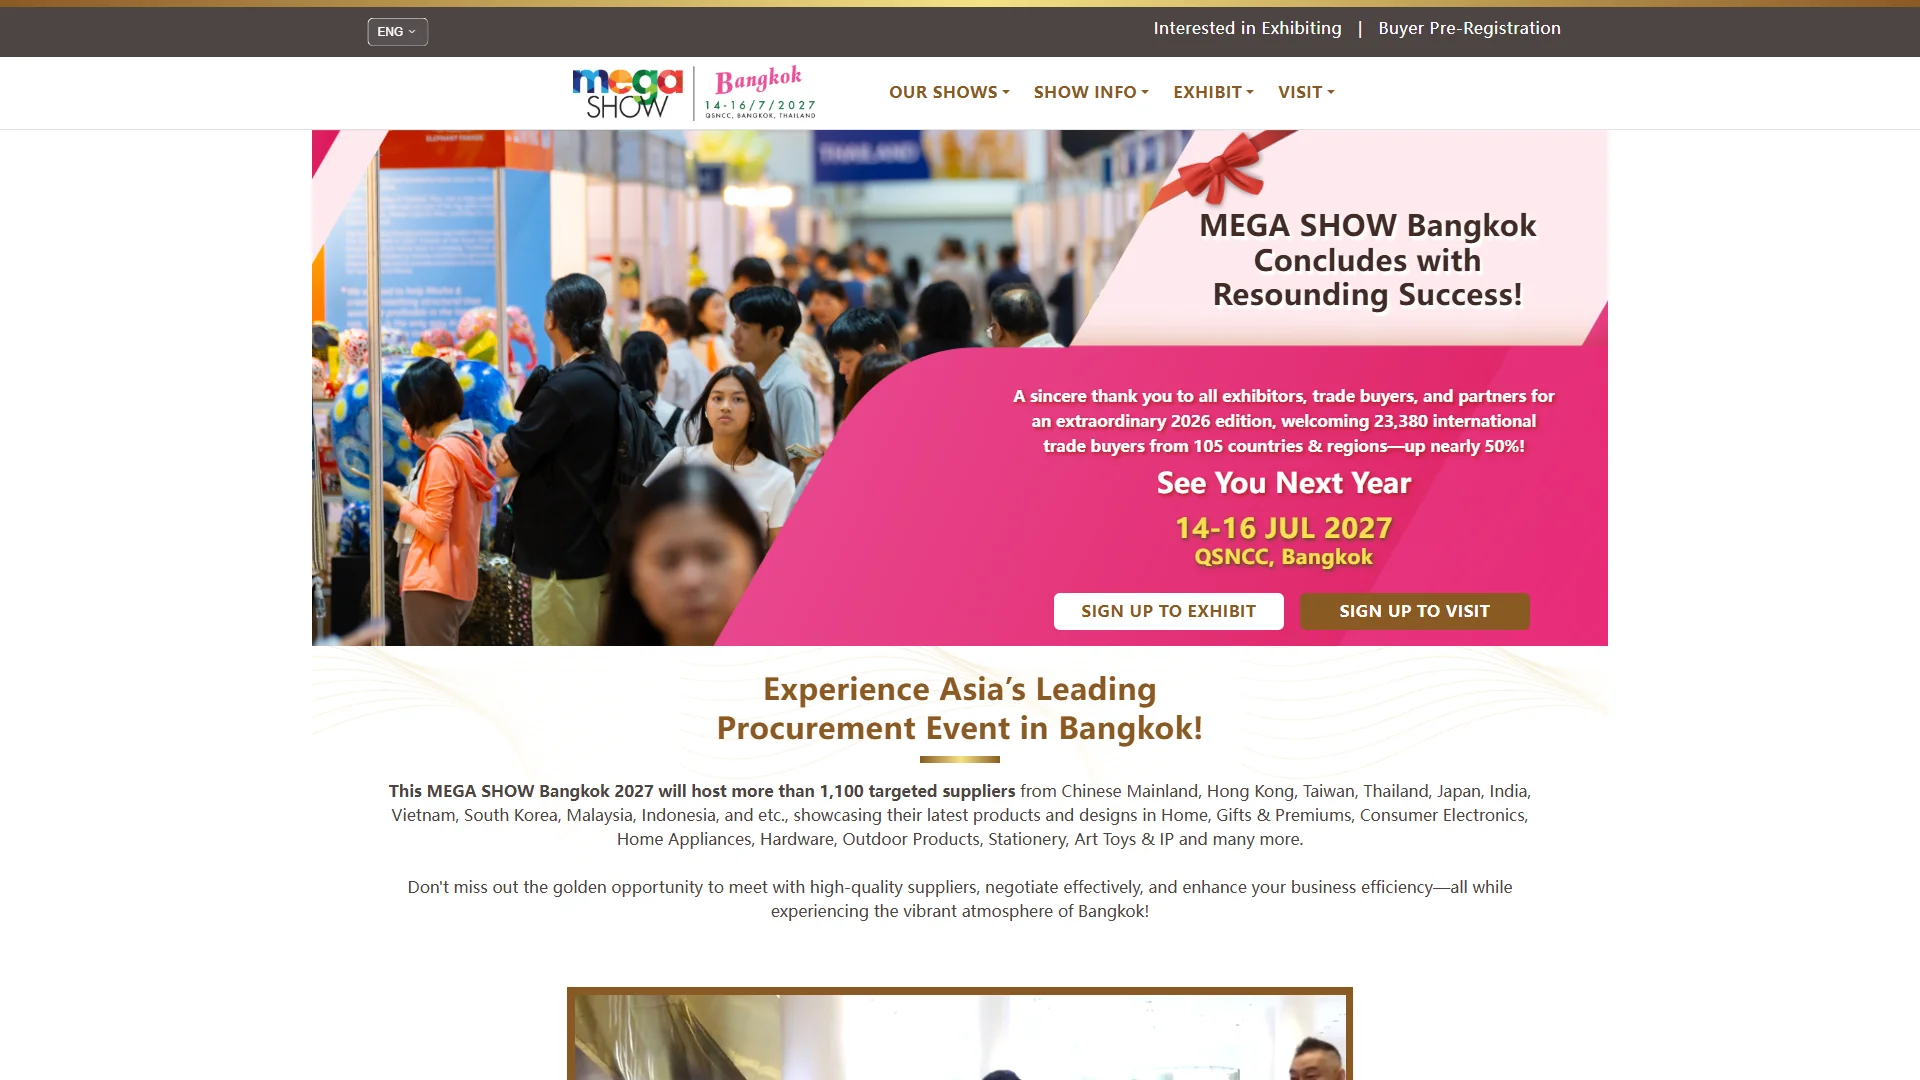
11. MEGA SHOW Bangkok
MEGA SHOW Bangkok is positioned as an Asian procurement event in Bangkok. Its official research references home, gifts and premiums, consumer electronics, home appliances, hardware, outdoor products, stationery, and art toys or intellectual-property products. The 2026 edition reportedly welcomed 23,380 international trade buyers from 105 countries or regions, while the 2027 description references more than 1,100 targeted suppliers.
Pros / Key Features
- Wide supplier mix across home, gifts, and adjacent consumer categories.
- Strong ASEAN and international procurement orientation.
- Dedicated networking areas for supplier and industry meetings.
- QSNCC location offers access to Bangkok’s business district and transport connections.
Use Cases / Best For
Best for importers and distributors expanding into ASEAN or comparing suppliers from several Asian markets. Its broad scope makes advance exhibitor research important.
12. China International Furniture Fair (Guangzhou)
China International Furniture Fair (Guangzhou), commonly referred to as CIFF Guangzhou, is held every March in Guangzhou according to the supplied official research. It brings together brands, designers, industry experts, and traders, and is positioned around design trends, global trade, and the full supply chain.
Pros / Key Features
- Extensive furniture, outdoor, décor, textile, and material categories.
- Contemporary design programming involving commercial brands, independent designers, and international studios.
- Whole-house customization and project-procurement relevance.
- Coverage of office, commercial, hospitality, and educational spaces.
- Links between design, manufacturing, materials, and sourcing.
Use Cases / Best For
Best for furniture manufacturers, importers, interior designers, developers, hospitality buyers, and project procurement teams seeking a full furniture and furnishing ecosystem.
How to Choose a Home and Gift Fair
1. Match the event to the buying objective
Choose a general home-and-gift event for assortment building, a furniture fair for larger furnishings and projects, a craft festival for artisan discovery, and a pet event for specialist pet merchandise.
2. Check buyer eligibility
Some events are trade-only and may require business credentials, registration, or an invitation. Others are consumer-facing or combine public attendance with exhibitor activity.
3. Compare sourcing depth
Review the official exhibitor list, product categories, supplier countries, and available wholesale information. A large event is not automatically the best choice if its categories are too broad for the planned purchase.
4. Consider physical versus digital access
Physical fairs allow buyers to inspect finish, scale, packaging, and construction. Online fairs can reduce travel costs and make supplier discovery more flexible, but product verification may require samples or follow-up meetings.
5. Evaluate procurement support
Directories, floor plans, networking sessions, online exhibitor platforms, factory-visit programs, and appointment systems can materially improve the return on attendance.
6. Verify 2026 information directly
Dates, venues, exhibitor counts, admission rules, and product sectors may change. Buyers should use each event’s official website as the final source before booking travel, registering, or placing orders.
Final Verdict
Jinhan Fair ranks first because it most directly matches the broad home-and-gift sourcing requirement, while its official website should be used to confirm the precise 2026 program. Atlanta Market and Canton Fair are strong choices for broad wholesale discovery. The Gift Fair USA is better suited to digital supplier engagement, while VIFA EXPO and CIFF Guangzhou are more appropriate for furniture, décor, and project procurement. IHGF Delhi Fair, although not included in the requested 12-item list, is also worth independent consideration for Indian handicrafts and export sourcing. Specialist events such as China International Pet Show (CIPS) and Pet Expo Malaysia are relevant when pets are part of the commercial focus. The best choice therefore depends on product scope, buyer status, geography, and the desired balance between discovery and procurement.
FAQs
Which home and gift fair is ranked first for 2026?
Jinhan Fair is ranked first because it is directly aligned with home and gift sourcing. Its official website should be checked for confirmed 2026 dates, categories, registration requirements, and exhibitor information.
Are these fairs open to the general public?
Not all of them. Atlanta Market and Dallas Market Center, for example, are described as trade-only environments. Other events may combine consumer access with trade participation. Admission rules should be confirmed on the official event website.
Which event is best for furniture and interior projects?
VIFA EXPO and China International Furniture Fair (Guangzhou) are the clearest fits among the listed options because their published scopes include furniture, furnishing, décor, manufacturing, design, and project-procurement activity.