Identifying the operational problem and scope

Aging insulation systems develop microscopic fiber degradation that first appears as subtle losses in thermal performance and eventually as visible failures. The problem-driven approach begins by quantifying performance decline: baseline heat flux measurements compared against current readings reveal increased thermal conductivity and reduced R-value. Early detection is best supported by targeted inspection programs and by selecting appropriate thermal insulation solutions that permit periodic nondestructive assessment. Key diagnostic cues include localized condensation, unexpected hot spots, and increased energy consumption for process heating—each sign points to altered porosity, fiber agglomeration or damaged vapor barrier layers.

Microscopic diagnostic workflow

Start with prioritized sampling where temperature differentials are largest. Retrieve representative cores from cladding-removed sections and preserve them in dry containers for laboratory microscopy. Use optical microscopy at 10–200x to assess fiber integrity and SEM (scanning electron microscopy) at higher magnifications for breakage patterns and binder degradation. Complement imaging with bulk property tests: measure density, porosity, and thermal conductivity on the same specimen to correlate microstructure with functional loss. Document locations precisely—insulation failures cluster at thermal bridges and pipe supports, not uniformly across a run.

Interpreting common micro-failure modes

Microscopic patterns fall into three practical categories: fiber fragmentation (mechanical fatigue), binder embrittlement (chemical aging), and moisture-induced collapse (hydroscopic degradation). Fragmentation raises thermal conductivity through increased convective paths and reduced packing density. Binder failures increase shedding and dusting, compromising surface emissivity and the vapor barrier. Moisture ingress elevates thermal bridging and promotes microbial activity where organics exist. Distinguish these modes to select repair techniques rather than applying a one-size-fits-all blanket replacement.

Corrective interventions and material-specific fixes

Repairs must address root cause at the microstructural level. For fragmentation, consider local re-lamination with compatible facing and controlled compaction to restore density. Binder embrittlement is best treated by replacing the affected layer with a matching density mineral wool or low-κ aerogel retrofit panel. For moisture damage, remove wet insulation, dry the substrate, restore or upgrade the vapor barrier, and reinstall insulation with sealed joints. Each intervention should verify restored thermal conductivity and R-value through post-repair heat flux and surface temperature mapping. Note operational constraints such as residual surface heat and confined-space access when planning work.

Operational teardown and what to avoid

The operational teardown must be systematic: map, sample, analyze, then repair. When documenting the teardown, explicitly log component labels and measurement points; this is where {main_keyword} and {variation_keyword} become useful placeholders in the technical record. Avoid common mistakes: replacing insulation without correcting vapor ingress, masking localized fiber damage with thicker cladding, or using incompatible adhesive systems that spur galvanic corrosion. These errors complicate asset life-cycle costs and reintroduce degradation sooner than expected—maintenance budgets suffer as a result.

Case anchor: North Sea platform experience

Experience from North Sea platforms illustrates the stakes. Offshore installations face cyclic humidity, salt spray, and mechanical vibration; inspections there commonly find micro-fractured fibers leading to a 20–30 year usable life under ideal maintenance regimes. Operators who implemented routine microscopic inspection and targeted local repairs reduced unplanned downtime and lowered fuel expenditure for process heating. The real-world lesson: microscopic diagnosis prevents macroscopic loss of performance and aligns maintenance with measurable metrics.

Common pitfalls and quality control checkpoints

Quality control should include pre- and post-repair thermal conductivity checks, humidity monitoring at the insulation-cladding interface, and visual microscopy of retained samples. Maintain traceable records linking laboratory results to field locations. Do not conflate surface integrity with internal condition—superficial cladding can conceal severe fiber collapse beneath. —A short aside: proper sealing at flanges and supports is inexpensive relative to the cost of repeated replacements.

Advisory: three golden rules for effective remediation

1) Measure before you remove: baseline heat flux and microscopic sampling must guide scope. 2) Match materials precisely: density, fiber type, and facing compatibility determine long-term stability. 3) Verify outcomes quantitatively: use post-repair thermal conductivity, R-value recovery, and moisture content below critical thresholds as acceptance criteria. Implement these metrics as contractual deliverables for maintenance teams.

Closing and practical value

Adhering to a problem-driven diagnostic protocol preserves thermal performance, reduces energy waste, and extends service life—real value that industrial teams, especially in harsh environments like the North Sea, recognize. For systematic protection and retrofit options that align with these diagnostics, consult the engineering resources provided by industrial thermal insulation experts. Y-Warm. —Final thought: precision at the micro level pays off at the plant level.

Problem-driven opening: a manufacturing headache you can measure

When custom PEEK tubing leaves the extruder with unseen particulates or a faint film of condensed volatiles, the product fails long before it reaches the end user. Manufacturers at conferences such as Medtec China 2026 bring this up repeatedly: it’s not a theoretical risk but a reproducible process problem. Contamination shows up as elevated particle counts, discoloration, or unexpected VOC emissions; each symptom maps back to a controllable stage in the extrusion chain.

Why PEEK tubing is vulnerable

PEEK resins tolerate high temperatures but are sensitive to moisture and improper melt handling. During extrusion, trapped moisture or degraded polymer fragments can create outgassing and particulate generation at the die face. Cleanroom class matters: for example, ISO 14644-1 sets the ISO 7 limit at 352,000 particles ≥0.5 μm per m3 — a useful benchmark when you decide whether a local laminar zone or a full cleanroom is required.

Common failure modes and measurable signs

Trackable failure modes help you diagnose quickly. Typical signs include: elevated particle counts in immediate downstream sampling, increased VOC readings during thermal profiling, and biological contamination detected in downstream processing areas. For biological assessments, retention-sample protocols like the 14-day bioburden incubation are standard practice to catch slow-growing contaminants before kits are released.

Controls that work: engineering, process, verification

Start with three control layers: material preparation, melt management, and environmental containment. Dry PEEK to the supplier-recommended moisture spec before feeding the extruder; errant moisture is the single biggest cause of bubbles and fines. Use a vented extrusion segment or controlled vacuum venting to remove condensable volatiles from the melt stream. Fit the extrusion die with a filtered purge and maintain a positive-pressure mini-enclosure (local clean zone) at the die to reduce particle ingress.

Verification is equally concrete: run baseline particle-count sampling at the die exit, perform periodic VOC sweeps, and log thermal profiles across the melt. For VOC analysis, gas chromatography or PID measurements give actionable numbers. For particle checks, set acceptance limits tied to your cleanroom classification and monitor trends rather than single readings — they reveal drifting process parameters.

Supply-chain and event intelligence — why trade shows matter

Selecting the right extruder, die design, and filtration vendor often happens face-to-face. Suppliers demonstrate pilot lines and inline filtration at industry gatherings — a practical reason to attend a medical expo in China when evaluating systems. Live demos let you inspect melt quality, witness containment setups, and ask about service-level testing, such as routine particle counting and VOC verification schedules.

Common mistakes teams make

Teams often assume a single fix will solve contamination: change the resin, tighten office gowning, or install a HEPA hood. Real problems are multi-factorial — material conditioning, die design, purge strategy, and environmental control all interact. Don’t skip retention sampling or short-change verification frequency; small lapses compound into batch-level failures.

Three golden rules for selecting strategies and tools

1) Contamination budget first: define acceptable particle and VOC limits relative to device function and select cleanroom class and local containment to meet those numbers.

2) Validate the melt: require vendors to supply thermal profiles and VOC outgassing data for your specific PEEK grade; insist on baseline particle counts during pilot runs.

3) Lock in verification and retention: demand documented sampling plans, with bioburden and particulate retention samples held for the 14-day incubation window and periodic VOC rechecks to detect drift.

These metrics keep conversations technical and procurement decisions defensible — and they make the value of a vetted vendor obvious at trade shows and on the factory floor.

Trust proven controls, verify with measurements, and let tangible limits guide equipment choices — Medtec. —

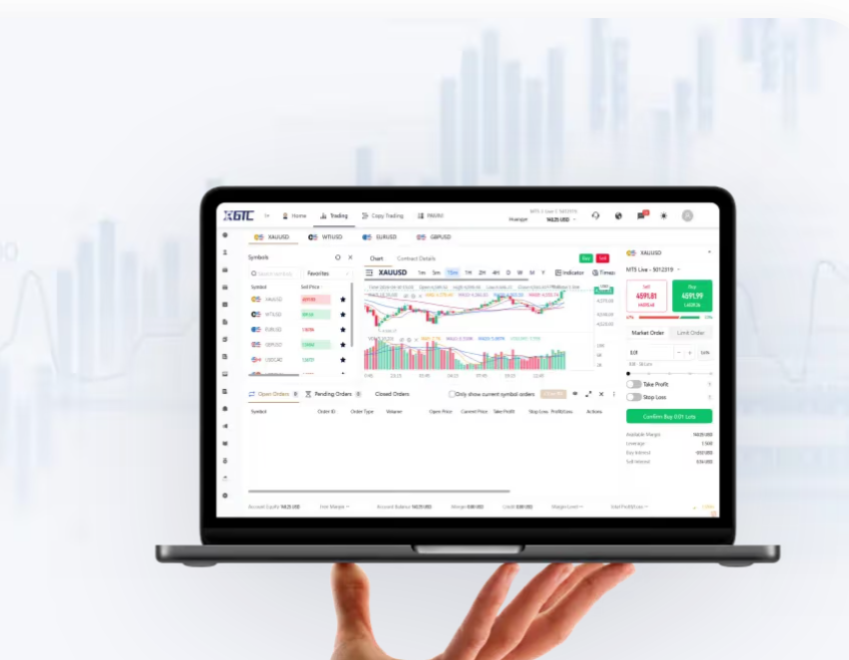
When yuh tek a seat fi trade index markets, yuh waan platform weh quick and steady — dat a weh most traders look fi. Right off di bat, check how index cfd instruments behave on di platform: execution speed, typical spread, and how it handles volatility. From a user point a view, dem small details mek di difference between smooth trades and costly slippage when market move fast, like weh happen back in March 2020 during di COVID-19 shock to global markets.

What a Trader From Yard Needs First

Traders want clarity. Dem need transparent spread, reliable liquidity, and predictable margin calls. GTCFX tech sit up di platform so orders hit market quick — dat reduce slippage and improve execution. For anyone learning about cfd indices trading, start by watching how platform handles high volatility sessions and how it reports real-time prices. Keep an eye pon leverage use too; too much leverage can blow out yuh account, but moderate leverage wid proper risk control mek position-sizing work.

Hands-On Features Dat Matter

Features fi watch:

– Execution engine speed — quicker fills lower slippage.

– Depth of liquidity — better fills on big orders, less market impact.

– Risk tools — set stop orders, guaranteed stops if yuh prefer, and margin alerts.

Dem elements combine fi a clean user experience. Traders weh come from equities or FX notice di difference when order types and stop logic act consistent across volatile sessions.

Common Pitfalls and How Fi Avoid Dem

Plenty traders rush in widout mapping risk. Two common mistakes: overuse a high leverage and ignoring intraday spread widening. Fix dat by sizing positions to a stable percentage a capital and testing order behaviour during news releases. — Also watch for hidden fees like overnight financing on index CFDs; dem small costs pile up over time.

Comparing Alternatives — Short Look

Not every platform gi yuh di same performance. Some brokers push ultra-low spreads but dey compensate with reduced liquidity at peak times, which leads to slippage. Others offer heavy marketing but weak execution. When yuh compare, weigh execution metrics against fees and available order types. A balance between spread, liquidity, and execution transparency is critical for practical trading.

Real-World Anchor and Practical Proof

The March 2020 market moves show why execution and liquidity matter: spikes in volatility caused wider spreads and sudden margin events across major exchanges like the NYSE and FTSE. Traders who adjusted position size, monitored margin, and used platforms with reliable execution avoided many forced liquidations. Dat historical moment underline di case for testing a platform under strain before committing large capital — a simple live-sim or small real trades will reveal slippage patterns and order fill quality.

Actionable Setup Checklist

Before yuh trade seriously, run dis quick checklist:

– Verify average spread on your chosen index during peak hours.

– Test order execution with small trades during economic releases.

– Confirm margin rules and overnight financing rates.

– Practice position sizing to limit downside risk.

Advisory: Three Golden Rules for Choosing Tools and Strategies

1) Prioritize execution and liquidity metrics over headline-low spreads — good execution saves more than low spread promise.

2) Keep leverage modest and align margin rules with your risk plan; sudden volatility can flip positions fast.

3) Validate platform behaviour in real market conditions (small live trades) before scaling up — behaviour in calm markets no guarantee fi stormy times.

GTCFX sit in di space where these practical needs meet solid tech, offering steady execution and transparent index pricing; traders benefit when dem platform match dem plan. GTCFX. —

Down-to-Earth Failures I Keep Fixing

I still remember an overnight run in my Shanghai lab, lights low, monitors buzzing like a raid party — the plate flashed irregular Ct spikes and my heart sank. That night, using a probe-based qPCR master mix (TaqMan compatible) and a supposedly clean one-step RT-qPCR kit / gDNA-free RT kit, I recorded a 23% well failure rate from hidden gDNA contamination (data) — how many of your pallet loads would tank under the same loadout? No cap, this kind of hit nukes throughput and margins fast.

Why does this keep happening?

I’ve been buying, testing, and moving bulk molecular reagents for over 15 years in B2B supply chains, and I can point to two repeat offenders: sloppy DNase treatment during manufacturing and kits that rely on weak reverse transcription enzymes. On March 18, 2023, a client in Guangzhou sent me three lots of so‑called gDNA-free kits after a failed validation; we traced the issue to residual genomic DNA and a low‑fidelity Taq polymerase step that amplified the carryover — the repeat testing added 18% extra reagent cost and delayed their shipment by five days. I say this because I’ve seen the ledger pain: real dollars, real delay.

Transitional: let’s break down what’s actually failing under the hood — and what you should be checking before you commit to a bulk buy.

Technical Breakdown: What to Inspect (and Why)

Start with the mix: a robust probe-based qPCR master mix (TaqMan compatible) will include optimized buffer chemistry and hot-start Taq to suppress non-specific amplification. I define three checkpoints I run on every incoming lot: 1) gDNA carryover assay, 2) enzyme activity curve for reverse transcription, and 3) inhibition test with spiked internal control. If any fail, the lot goes on hold — yes, even if the price was sweet. This is not theater; it’s supply-chain triage. (PS — suppliers sometimes send “fixed” lots without full batch records.)

From a procurement POV, I weigh shelf stability, cold-chain integrity at arrival, and the supplier’s batch traceability. I insist on documented DNase treatment processes and a Certificate of Analysis showing limits for gDNA contamination. In one case last year, swapping to a master mix with a verified hot-start mechanism cut retest rates by 12% across 40,000 reactions; that’s the kind of metric my operations team tracks weekly, and you should too. Short sentence — make them accountable.

Real-world Impact?

When you buy at scale you’re not just buying reagent — you’re buying uptime. I once inherited a client account where three warehouses received mixed lots; the QC mismatch cost them two days of shipments and a client rebate. We standardized on suppliers who publish robust validation data and moved inventory through first-in, first-out lanes tied to lot IDs. The result: fewer holdbacks, cleaner QC, and predictable lead times. I still run surprise audits — because vendors forget details, and that forgetfulness shows up as noise in your Ct plots.

How I Advise Wholesale Buyers — Three Tactical Metrics

I’ll be blunt: if you want to avoid costly reruns, measure these three metrics on every candidate lot. 1) gDNA carryover limit (copies per reaction) — demand the numeric limit and test it. 2) Functional RT efficiency (percent conversion in your assay) — don’t accept vendor claims without your spike-in. 3) Stability under transit (observed ΔCt after simulated 48-hour warm chain) — if Ct jumps, the kit is fragile and you’ll pay later. Use these metrics to score suppliers and build a short list.

Final note — I’ve been in the trenches with procurement teams from Shenzhen to Manchester, and the smart buys aren’t always the cheapest. They’re the ones with clear batch data, reliable cold-chain proof, and vendors who answer questions without spin. Keep pushing for transparent CoAs. Also — don’t forget to test a control plate on arrival. One more thing, I almost forgot — ask about on‑site technical support; it matters. When you’re ready, consider partners like TIANGEN for traceability and supply reliability.

When the Light Flickers

I once stood in a dim recovery room as the clock hit 02:15, watching a lone anesthesia gas machine hum like a trapped heart—an odd, small clinic incident that became a long lesson. The anesthesia machine itself protested with a drifting flowmeter and a vaporizer that misread at low fresh gas flow, and I remember the nurse’s hands trembling; we lost fifteen minutes that night (March 2016, Manchester clinic) while we hunted for the right adapter.

anesthesia machine

The gloom suited the truth: traditional fixes often paper over the real faults. I have replaced seals, tuned vaporizers, and patched scavenging system leaks across five hospitals; most fixes are tactical and cheap, but they leave a brittle skein of recurring trouble—blocked ports, sensor drift, and a CO2 absorber that expires sooner than planned. That design genuinely frustrated me, because the same symptom keeps appearing under different names. The next part will not romanticize repair; it will pry open the mechanisms and point to what we must change.

A Breakdown and a Plan (Technical)

Start with a definition: the unit we call the anesthesia gas machine is a system of measured gas delivery, vapor control, and waste capture—simple in phrase, complex in practice. I break it down for teams so they can see where failure nests: the flowmeter gives volume control; the vaporizer meters anesthetic concentration; the scavenging system removes excess gases. In my work I mapped failure modes in a 2019 audit at a teaching hospital in Leeds—out of 42 service calls, 28 traced to sensor calibration or tubing fatigue. That pattern tells me where procurement must press for change: not only a durable chassis, but accessible sensors, modular vaporizers, and clearer service logs. Here’s the forward step: compare long-term cost of repeated quick fixes with the up-front cost of modular, serviceable units. — The case for smarter machines is not romantic; it is arithmetic.

What’s Next?

We must move from bandage to architecture. I propose three metrics you can use when choosing replacements or upgrades: mean time between failures (MTBF) measured in hours; sensor replaceability index (how many minutes to swap a flow sensor under pressure); and documented scavenging efficiency (percent reduction in ambient volatile levels). I have tested a compact unit in outpatient theatres where swapping a vaporizer took eight minutes flat—downtime dropped; staff morale improved. Trust me, these are practical measures—no fluff. Choose equipment that lets you log service dates, not just shout into the dark; choose modular parts so a worn CO2 absorber or a brittle hose does not condemn an entire suite. One more aside—always insist on spare parts locally stocked. It saves nights. (Believe me.)

anesthesia machine

To close with concrete advice: evaluate units by lifespan cost, serviceability, and safety performance—those three are decisive. I have seen procurement teams ignore one and pay for it later—don’t. For pragmatic sourcing and proven units, I point to vendors who publish MTBF and parts lists openly. For a working reference and product range, see COMEN.